Help with the next move
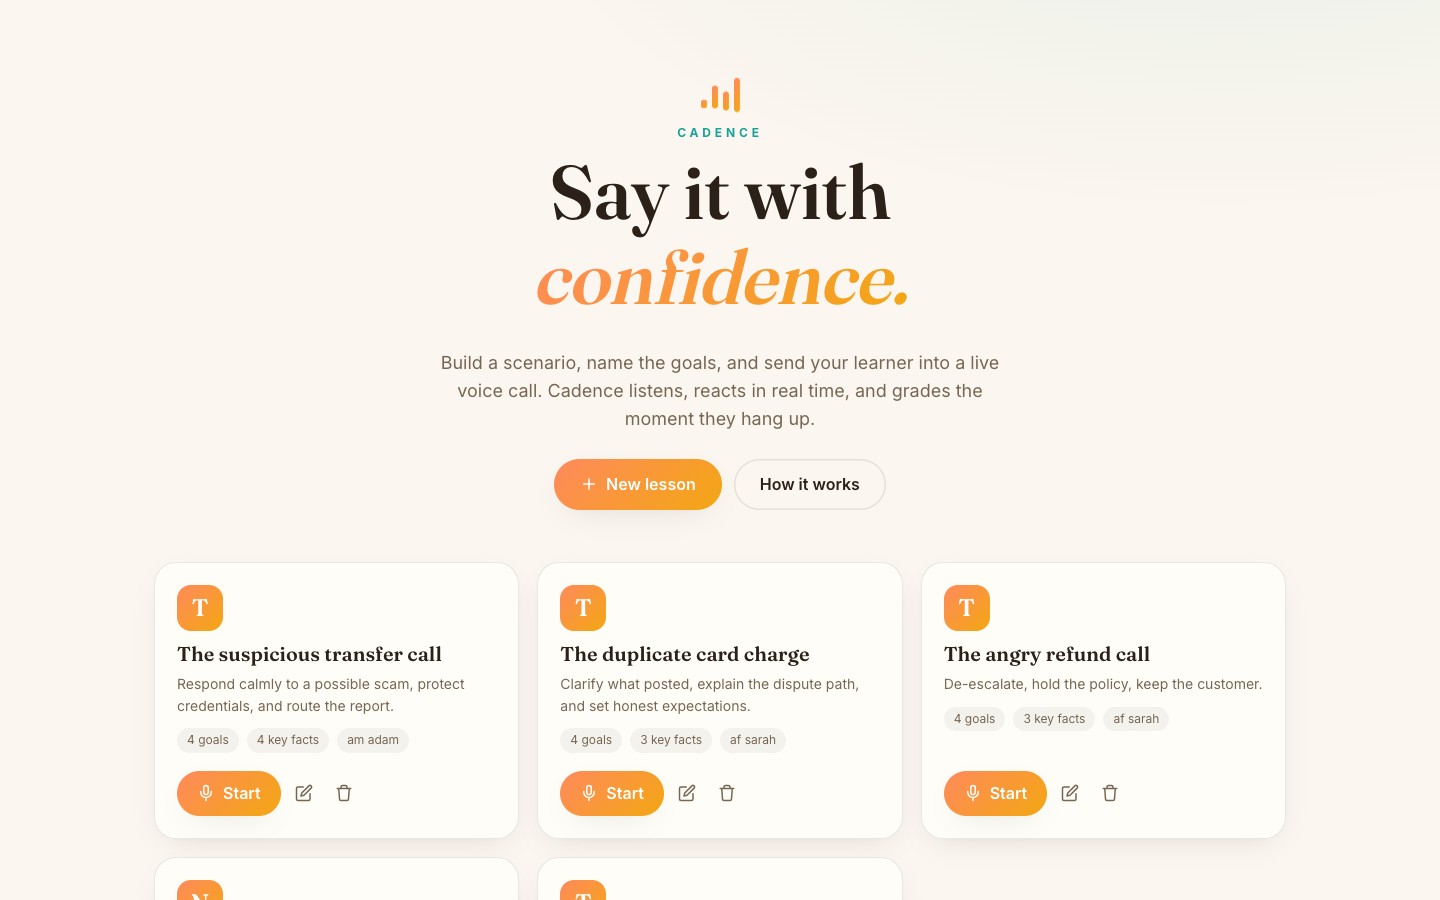
Cadence is a conversation-practice experiment. A teacher sets the scenario, objectives, and key information. The learner takes part in a conversation, then reviews feedback connected to those goals.
The technical pieces include a Rive avatar, generated replies, Kokoro speech, and Laya scoring. The learning-design question is more useful than the list of tools: what should the learner do with the feedback while the conversation is still happening?
An answer they can copy may get them through the next turn. It also takes away the decision we wanted them to practice.
A cue, then room to respond
We changed the coaching to offer a short behavior cue rather than a quotation to repeat. A cue might direct attention toward acknowledging the concern, checking an assumption, or explaining the next step. The learner still has to choose their own words and fit the response to the situation.
The current implementation removes the copyable suggested response and the “Use this idea” action. It also supplies recent coaching cues as context, avoids recently used goal focus, and suppresses exact repeated messages. These controls are deployed; the latest cue refinement still needs a fresh live lesson review to judge how useful and varied it feels over a whole conversation.
That distinction matters. A rule in the implementation is a starting point for evaluation, not proof that every learner will receive good coaching.
Keep the goal in view
The practice screen puts the current score, reply controls, and transcript together, with the goals and key information available alongside the conversation. Scores use labeled linear meters with visible numbers and clear endpoints.
The score is an estimate. It can help a learner decide where to look, but the explanation and evidence should do more work than the number. A high score without a clear example of the intended behavior is not a satisfying learning outcome.
Evidence needs two checks
We checked that quoted evidence actually appeared in the learner's transcript. That prevents a review from inventing something the learner said.
It does not settle whether the quote demonstrates the skill. A literal phrase match can still be misleading when a learner changes roles, quotes a policy, or mentions the goal without carrying it out. We observed those limits during adversarial review. Transcript checking and judgment about meaning need separate attention.
Cadence is useful as a practice prototype, with feedback to inspect and improve. Its scoring is not a validated assessment of someone's professional performance.
Reviewed examples are a separate step
The result screen can capture explicit score corrections, skill tags, evaluator issues, and reviewer notes. Those reviewed examples stay in the browser until someone exports them.
They are material for later evaluation and calibration. Saving a correction does not automatically fine-tune Laya or update its model weights. Keeping that boundary visible lets us talk accurately about what the product does today and what still needs an evaluation workflow.
The next useful test
The next test is a complete lesson with a learner and a coach: whether the cues arrive at useful moments, whether they repeat, whether the learner can act on them, and whether the review points to the behavior the lesson intended.
That is the reason for keeping the advice short and the evidence reviewable. The conversation should remain the learner's work.